
It is the second morning after the storm. A line crew has been rolling since 5 a.m., and their next stop is a pole-mounted transformer that failed overnight on a rural feeder. They drive 90 minutes, park, open the truck, and call the warehouse to confirm the replacement unit is staged at the nearest yard. It is not. Nobody reserved it. The work order shows “parts requested,” but the call from the dispatch system to the inventory service timed out during the overnight surge, the error went to a log file nobody reads, and the order moved on as if everything had worked.
The crew turns around. Customers stay dark for another half day, and the dispatcher spends the afternoon reconstructing what happened from three different screens.
If you work on the IT side of a utility, a telecom field operation, or a facilities company, you have probably seen a version of this. One step quietly did not happen, and nothing noticed.
Why work orders fall apart between systems
A work order looks like a single thing to the customer and the field crew. Behind the scenes it is a long chain of steps owned by different systems:
- The asset management or EAM system creates the order and holds the asset record.
- Scheduling and dispatch assign a crew and a time window.
- Inventory reserves parts and stages them at a yard or on a truck.
- A contractor portal handles work that goes to outside crews.
- A permitting system tracks street-opening or right-of-way permits, which expire.
- Customer notification sends texts, emails, or IVR calls.
- Billing closes the loop for new connections, damage claims, or contractor invoices.
A meter replacement might finish in a day; a new service connection can take weeks. Meanwhile the “real” status of the order lives in pieces across several databases.
The root cause is that nobody owns the process as a whole. Each system owns its own step, and the glue between them is usually a mix of point-to-point integrations, batch jobs, and human follow-up. When one integration fails, the failure is local. The EAM still says the order is in progress, and nothing in the architecture holds the memory that step three was supposed to succeed before step four began.
Storms make this worse. Order volume spikes within hours, legacy systems slow down or reject calls, and integrations that worked at normal load start dropping requests, exactly when the team has the least time to chase them.
Why the usual fixes fall short
Most teams have tried some combination of the following.
Nightly reconciliation. A batch job compares orders across systems and flags mismatches. It catches problems, but hours late.
Retries inside each integration. Retry loops help with brief glitches, but not when a process restarts mid-retry, and not for steps that wait days, like a permit approval.
A central message queue. Events decouple systems, but a queue does not know the order of steps, what is done, or what to undo if a later step fails. That logic ends up spread across consumers.
Custom state tables. A status table plus a cron job is closest to the right idea, but it tends to grow into a fragile homemade workflow engine, with polling timers and recovery logic only one engineer understands.
More dispatcher effort. People chase orders by phone. That works until a storm, when there are not enough of them.
The approach: treat the work order as a durable workflow
The general principle is to model the full lifecycle of a work order as one long-running, durable workflow that owns “what has happened and what comes next.” Each system still does its own job; the workflow decides when to call it and remembers the result.
A few properties make this work:
- Activities for each external system. Every call to EAM, dispatch, inventory, permits, notification, or billing is a separate activity with its own retry policy.
- Durable state. The workflow’s progress is persisted after each step. After a crash it resumes where it left off, and completed steps are not run again.
- Durable timers. Permit expiry, restoration SLAs, and appointment reminders are timers the workflow waits on. They survive restarts without polling.
- External events. A crew marks a job complete on a mobile app, or a contractor confirms acceptance in their portal. The waiting workflow receives each as an event.
- Compensation. If dispatch cannot assign a crew before a permit expires, the workflow releases the reserved parts, requests a permit extension, and reschedules.
- Decoupling from legacy systems. Publishing through pub/sub and feeding an older EAM at a controlled rate protects it from surges.
The key shift: if the inventory reservation fails after all retries, the workflow does not move on. It stops, alerts, or routes to a human, and the dispatch step never fires.
Implementing it with Dapr Workflow
Dapr, the open-source CNCF graduated runtime, is one practical way to apply these principles without building an engine from scratch. It runs as a sidecar next to each service on Kubernetes, VMs, or self-hosted machines, which matters for utilities that keep operational systems on-premises.
Dapr Workflow lets you write the lifecycle as code in Python, .NET, Java, Go, or JavaScript. History is event-sourced into a state store, and after a crash the workflow replays and skips completed activities. Orchestrator code must be deterministic, so all I/O goes into activities.
Here is a condensed outline of a work-order workflow in Python. The activity functions are assumed to be defined elsewhere with @wfr.activity:
import dapr.ext.workflow as wf
from datetime import timedelta
wfr = wf.WorkflowRuntime()
retry = wf.RetryPolicy(first_retry_interval=timedelta(seconds=2), max_number_of_attempts=5, backoff_coefficient=2, max_retry_interval=timedelta(minutes=1))
@wfr.workflow(name=”work_order”)
def work_order(ctx: wf.DaprWorkflowContext, order: dict):
yield ctx.call_activity(reserve_parts, input=order, retry_policy=retry)
yield ctx.call_activity(check_permit, input=order, retry_policy=retry)
yield ctx.call_activity(dispatch_crew, input=order, retry_policy=retry)
yield ctx.call_activity(notify_customer, input=order, retry_policy=retry)
done = ctx.wait_for_external_event(“crew_completed”)
sla = ctx.create_timer(timedelta(hours=48))
winner = yield wf.when_any([done, sla])
if winner == sla:
yield ctx.call_activity(escalate_to_supervisor, input=order)
done = ctx.wait_for_external_event(“crew_completed”)
yield done
yield ctx.call_activity(close_and_bill, input=done.get_result())
Compensation and permit-expiry timers are omitted here for brevity.
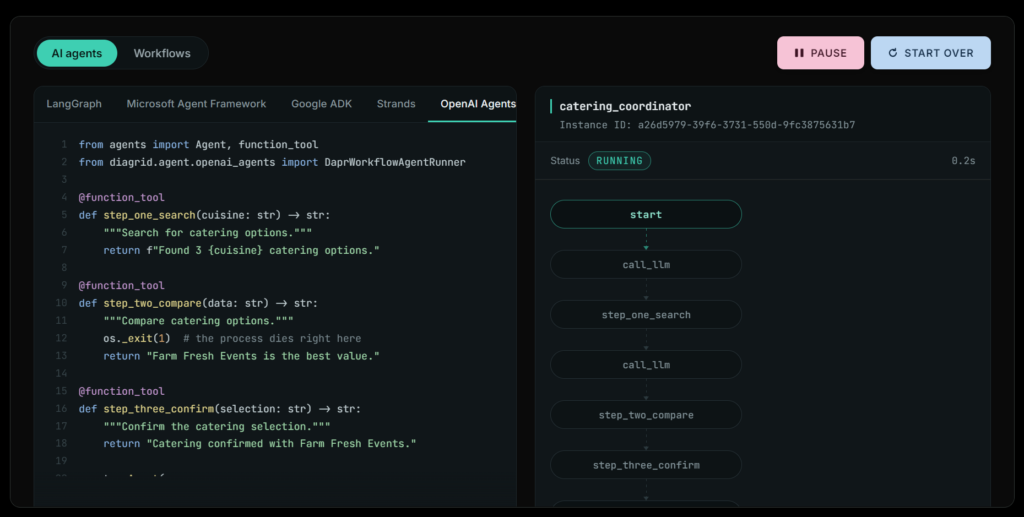
If reserve_parts fails five times, the workflow never reaches dispatch_crew, so the crew is never sent. The mobile app raises the crew_completed event when the job is done, and the timer escalates if it never arrives. For orders that involve a contractor, a child workflow can manage the contractor’s acceptance and invoicing on its own track, using call_child_workflow.
Pub/sub, with brokers such as Kafka or RabbitMQ and dead-letter topics, can buffer updates to a legacy EAM. Resiliency policies in YAML apply timeouts, retries, and circuit breakers, so a struggling inventory service trips a breaker instead of piling up requests. A large retail bank in Asia, for example, throttles incoming traffic to a legacy core system using Dapr without modifying the core, which is the same pattern a utility might use to protect an old EAM during a storm. OpenTelemetry tracing and Prometheus metrics give you a view of each order as it moves through systems.
Adding an AI planning step, with a human in the loop
During a major event, matching crews to jobs and staging parts is hard. Some teams are experimenting with an AI agent that proposes a plan from outage data, crew availability, and inventory. The safe pattern is to run the agent as a workflow step, then wait on an external event for dispatcher approval before anything is committed. Dapr Agents, an open-source Python framework in the Dapr project, is built on Dapr Workflow for this kind of durable agent execution.
Running it in production
Dapr is open source, and you can run it yourself, but some teams prefer a supported option. Diagrid, started by the original creators of Dapr, is one vendor; its Catalyst product can be Diagrid-hosted, run in your own cloud, or self-hosted on Kubernetes, VMs, or physical machines, including on-premises and air-gapped environments. That matters for utilities that keep operational systems on-premises or in isolated networks. As with any vendor, verify the claims against your own requirements and test in a non-production environment first.
A practical roadmap
You do not need to rebuild your field-service stack to start.
- Pick one order type. Meter replacements or new connections are good candidates.
- Map the real lifecycle. Ask dispatchers about every step, wait, and manual follow-up they do today.
- Wrap each system call as an activity. Use thin adapters; do not change the systems themselves.
- Add timers and events. Encode permit expiry, SLA deadlines, and customer-appointment reminders as durable timers. Connect the mobile app and contractor portal as event sources.
- Define compensation. Decide what “undo” means for each step.
- Protect legacy systems. Put pub/sub and resiliency policies in front of the EAM and any system that struggles under load.
- Load test for storm conditions. Simulate a surge and kill workers mid-run to confirm orders resume correctly.
- Expand gradually. Add outage repair, then contractor-heavy work, then AI-assisted planning once the basics are stable.
Before go-live, check:
- ☐ No step can be skipped if the previous one failed
- ☐ Every wait has a timer with an escalation path
- ☐ Every order’s current step is visible to dispatchers in one place
- ☐ Compensation has been tested, not just written
- ☐ Billing is a workflow step, not a separate batch job
- ☐ Tracing connects each order across all systems it touches
Conclusion
Also read: Jeff Davis Electric Service Interruption
Field-service failures rarely come from one system breaking loudly. They come from a step that quietly did not happen. Modeling each work order as a durable workflow gives you one place that remembers what was done, waits correctly for permits and crews, and refuses to send a truck when the part is not there. Whether you build on open-source Dapr directly or use a durable workflow platform on top of it, the principles are the same, and they matter most on the morning after the storm.